Hugo Deleted Pages Still Online: Audit Stale HTML with Python
On this page
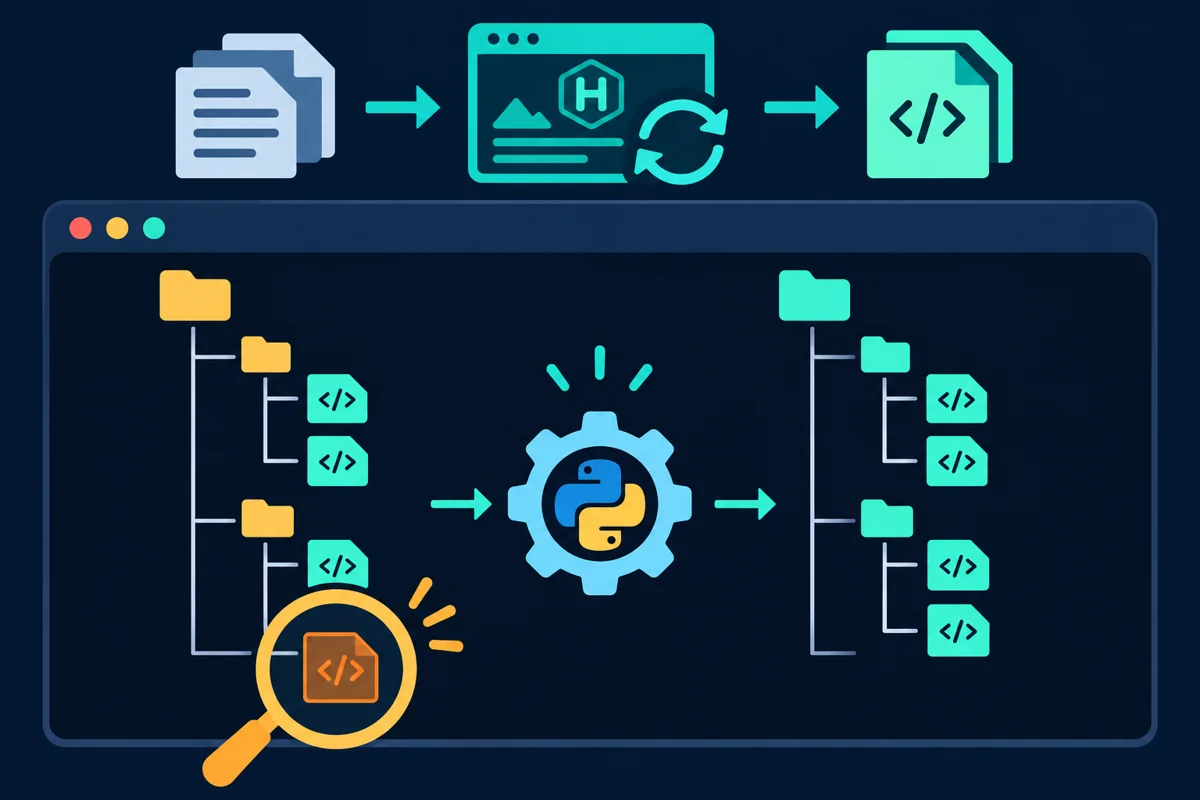
You deleted a Markdown file and rebuilt with Hugo, but its old URL still works. Before clearing browser caches, check whether the old HTML is still on disk. This beginner-to-intermediate tutorial reproduces stale output in a separate demo site, then uses Python to compare HTML path inventories from an existing output and a fresh build.
The checker only reads directories: it never deletes, synchronizes, or publishes files. This is about an extra old artifact, not a post excluded by draft or date settings.
1. Method: check for the old file first
Hugo’s basic usage guide explains that a normal build does not empty its destination first. It overwrites matching output files but may leave files that are no longer generated. Deleting content, changing a permalink, or making a published page a draft can therefore leave old HTML behind.
First reproduce the problem, then test the cleanup flag on a disposable copy. For a real project, start with a completely fresh build directory to establish the expected file set and review extra paths in the old output. Do not point a cleanup command straight at your live directory.
2. Setup: create an isolated demo site
Use existing Hugo and Python 3.10 or newer installations; no packages are required. Commands were tested on Linux with Hugo 0.164.0 and Python 3.11.4 and assume bash/zsh. Use a new directory name when repeating the experiment. Run all subsequent commands inside hugo-stale-demo; do not run the initialization code at the root of a real site.
- Create minimal configuration, templates, and one temporary article:
hugo version
python3 --version
mkdir hugo-stale-demo
cd hugo-stale-demo
mkdir -p content layouts/_default static
cat > hugo.toml <<'TOML'
baseURL = 'https://example.org/'
title = 'Stale output demo'
disableKinds = ['taxonomy', 'term', 'RSS', 'sitemap']
TOML
cat > layouts/_default/single.html <<'HTML'
<!doctype html><html><head><title>{{ .Title }}</title></head>
<body><h1>{{ .Title }}</h1>{{ .Content }}</body></html>
HTML
cat > layouts/_default/list.html <<'HTML'
<!doctype html><html><head><title>{{ .Title }}</title></head>
<body>{{ range .Pages }}<a href="{{ .RelPermalink }}">{{ .Title }}</a>{{ end }}</body></html>
HTML
cat > content/old.md <<'MARKDOWN'
+++
title = 'Old page'
+++
Only a disposable demo page.
MARKDOWN
An empty static directory is included for compatibility with the cleanup behavior in the tested version. These templates only produce files we can check; there is no theme, network resource, or real site configuration.
3. Reproduce and fix: removing source does not remove output
- Build once, delete only the demo article just created, and rebuild into the same directory:
hugo --quiet --destination out-existing
test -f out-existing/old/index.html
python3 - <<'PY_DELETE'
from pathlib import Path
Path("content/old.md").unlink()
PY_DELETE
hugo --quiet --destination out-existing
test -f out-existing/old/index.html && printf 'STALE: old/index.html\n'
Expect STALE: old/index.html. This establishes a local disk problem before browsers or CDNs are involved. A demo without a 404 template may emit missing-layout warnings; this example checks only the home and article pages.
- Copy the output and test cleanup on the copy.
out-cleanedmust not exist:copytreerefuses to overwrite an existing directory.
python3 - <<'PY_COPY'
import shutil
shutil.copytree("out-existing", "out-cleaned")
PY_COPY
hugo --quiet --cleanDestinationDir --destination out-cleaned
test ! -f out-cleaned/old/index.html && printf 'CLEAN: old/index.html absent\n'
Expect CLEAN: old/index.html absent; the original out-existing still retains the old page. The Hugo command reference lists --destination and --cleanDestinationDir. The latter can remove manually added files from the destination: it is not a safe filter that only deletes old articles. Cleanup details vary across versions, so test on a copy first.
4. Implementation: compare HTML inventories without writing
Save this as audit_output.py in the current directory:
"""Compare HTML path inventories, without modifying either tree. Python 3.10+."""
import argparse
import json
import os
from pathlib import Path
import stat
import sys


def scan_error(error):
    raise error


def html_paths(root):
    result = set()
    for folder, dirs, files in os.walk(root, onerror=scan_error, followlinks=False):
        for name in dirs + files:
            if (Path(folder) / name).is_symlink():
                raise ValueError(f"symbolic link not allowed: {Path(folder) / name}")
        for name in files:
            path = Path(folder) / name
            if path.suffix.lower() != ".html":
                continue
            if not stat.S_ISREG(path.stat().st_mode):
                raise ValueError(f"not a regular HTML file: {path}")
            result.add(path.relative_to(root).as_posix())
    return result


def directory(value):
    path = Path(value)
    if path.is_symlink():
        raise ValueError(f"symbolic link not allowed: {path}")
    path = path.resolve(strict=True)
    if not path.is_dir():
        raise ValueError(f"not a directory: {path}")
    return path


def main():
    parser = argparse.ArgumentParser(description=__doc__)
    parser.add_argument("--existing", required=True)
    parser.add_argument("--fresh", required=True)
    args = parser.parse_args()
    try:
        existing = directory(args.existing)
        fresh = directory(args.fresh)
        if existing == fresh or existing in fresh.parents or fresh in existing.parents:
            raise ValueError("directories must be separate and non-nested")
        old_paths, new_paths = html_paths(existing), html_paths(fresh)
        if not new_paths:
            raise ValueError("fresh build has no HTML files")
        extra = sorted(old_paths - new_paths)
        missing = sorted(new_paths - old_paths)
        print(json.dumps({"extra_html": extra, "missing_html": missing},
                         ensure_ascii=True, sort_keys=True))
        return 1 if extra or missing else 0
    except (OSError, ValueError) as error:
        print(f"ERROR: {error}", file=sys.stderr)
        return 2


if __name__ == "__main__":
    raise SystemExit(main())
This checks relative paths, not file contents, sizes, or modification times. extra_html lists HTML candidates present only in the existing directory; missing_html lists HTML present only in the reference build. Different contents at the same path are not detected.
The os.walk documentation notes that directory scanning errors may be ignored by default. Here, onerror stops the check, and symbolic links in the scanned trees are rejected. An incomplete scan must not become a pass. Use trusted local directories that do not change during the scan; this is not protection against hostile paths or concurrent replacements.
5. Validation: distinguish differences from scan failures
- Check the arguments, then compare the original output with the cleaned copy:
python3 audit_output.py --help
if python3 audit_output.py --existing out-existing --fresh out-cleaned; then
    status=0
else
    status=$?
fi
printf 'exit=%s\n' "$status"
Expect the following, apart from the --help output:
{"extra_html": ["old/index.html"], "missing_html": []}
exit=1
- Exit codes follow this contract. A scan failure writes a diagnostic only to standard error, with no success JSON:
| Exit code | Meaning |
|---|---|
0 |
Both HTML path sets match. |
1 |
Extra or missing HTML paths need review. |
2 |
Invalid arguments, missing or overlapping directories, symbolic links, an empty reference inventory, or scan failure. |
This is not an automatic deletion list. Manually added HTML, legitimate legacy pages, and pages generated with different settings also become candidates. Confirm their purpose and your publishing policy first.
6. Automation: create a fresh reference every time
Save this as preview_check.py beside audit_output.py. It invokes Hugo from the current project root and neither clears nor rebuilds the directory supplied as --existing:
"""Build into a fresh temporary directory, then audit an existing output."""
import argparse
from pathlib import Path
import subprocess
import sys
from tempfile import TemporaryDirectory

parser = argparse.ArgumentParser(description=__doc__)
parser.add_argument("--existing", default="public")
parser.add_argument("--config", default="hugo.toml")
args = parser.parse_args()

workspace = Path("/tmp/codex-work")
workspace.mkdir(parents=True, exist_ok=True)
with TemporaryDirectory(prefix="hugo-output-", dir=workspace) as temporary:
    preview = Path(temporary) / "site"
    subprocess.run(
        ["hugo", "--quiet", "--config", args.config,
         "--destination", str(preview)],
        check=True, timeout=120,
    )
    result = subprocess.run(
        [sys.executable, "audit_output.py", "--existing", args.existing,
         "--fresh", str(preview)],
        check=False, timeout=120,
    )
    raise SystemExit(result.returncode)
- Run it in the demo site:
python3 preview_check.py --existing out-cleaned
if python3 preview_check.py --existing out-existing; then
    status=0
else
    status=$?
fi
printf 'exit=%s\n' "$status"
The first command should print two empty lists and return 0. The second should report old/index.html and print exit=1. TemporaryDirectory cleans up this reference directory when its context exits. Build failures or timeouts prevent comparison, and the existing output stays unchanged. Do not rely on cleanup after a forced kill or power loss.
- For your own project, place both Python files at its root and explicitly select the real configuration, for example
python3 preview_check.py --config hugotest.toml --existing public. The reference must use the same source, languages, configuration, environment variables, and build options. Do not scan while another build is writing. Increasetimeout=120for a slower build rather than removingcheck=True.
After reviewing differences, run the internal link and image checker on page references and the sitemap checker on the current publishing inventory. Verify removed paths over HTTP separately after deployment: a local pass does not mean an old live page is gone.
7. Troubleshooting: act on the source of each difference
| Symptom | Direct action |
|---|---|
Nonempty extra_html |
Check for deleted sources, changed URLs, or newly drafted content. Identify manually maintained pages before deciding between targeted removal and deploying a complete new directory. |
Nonempty missing_html |
Check comparison direction, build configuration, and deployment steps. These entries are not automatically cache problems. |
symbolic link not allowed |
Use build output in independent, real directories. Do not automatically follow links just to bypass the check. |
fresh build has no HTML files |
Check templates, content eligibility, and destination. An empty reference does not prove that every existing file should be removed. |
| Local old page is gone but HTTP still returns its body | Confirm the directory actually served and inspect the response body, then investigate incomplete deployment, a proxy, or CDN cache. A status code alone is insufficient. |
The checker scans only .html suffixes, case-insensitively. It does not check images, XML, CSS, JSON, server rewrites, or output content correctness. Path sets stay in memory, making it suitable for small and medium static sites.
8. Summary
Check for stale HTML locally, then use a fresh build as the reference to separate caching symptoms from files left behind during deployment. Keep the audit read-only, fail with a nonzero exit code, and deploy separately after review. A successful build alone does not prove an old URL has been taken offline.
- Author: yanzhi
- Original article: https://www.bobobk.com/en/hugo-stale-public-files-python.html
- License: This work is licensed under CC BY-NC-ND 4.0. See the license for attribution, noncommercial use and no-derivatives terms.
Related articles
- Check Executable Paths with Python shutil.which Before Automation Runs
- Missing Hugo Posts: Diagnose Drafts, Publication Dates, Expiry, and Output Paths
- Troubleshoot Linux Scheduled Jobs: Python Paths, Working Directories, and Environment
- Python subprocess Wildcards Not Expanding: Arguments, Spaces, and Redirection
- Compare File Contents with Python filecmp: Avoid Shallow Checks and Stale Cache