Hugo 删文后旧页面还在:用 Python 对比全新构建与残留 HTML
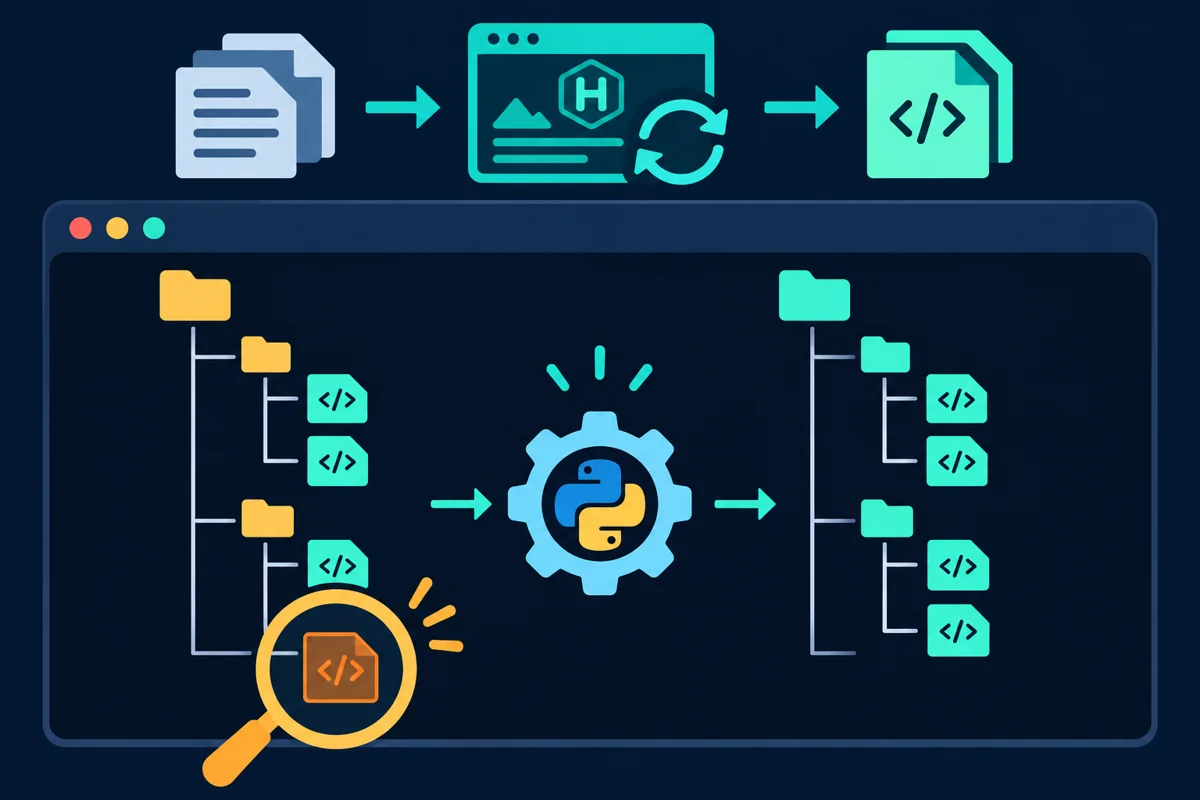
Markdown 已经删除,重新运行 Hugo 后,旧地址却还能打开。先别急着清浏览器缓存:旧的 HTML 可能根本没有从输出目录消失。本文面向初级到中级读者,用一个独立小站复现残留文件,再用 Python 对比已有输出与全新构建的 HTML 路径清单。
检查器只读目录,不自动删除、同步或发布。它解决的是“多了一份旧产物”,不是文章因草稿或日期而没有生成的问题。
1. 方法:先确认旧文件是否还在
Hugo 基础用法说明,普通构建不会先清空目标目录;它覆盖同名产物,但可能保留已经不再生成的文件。因此删文、改永久链接或把已发布文章改回草稿后,旧 HTML 仍可能留在原处。
本教程先复现,再在可丢弃副本上演示清理参数。实际项目更适合先构建到一个全新的目录,确认当前应该有哪些文件,再审查旧目录多出的路径。不要把清理命令直接指向线上目录。
2. 准备:建立独立演示站
需要已有的 Hugo 和 Python 3.10 或更新版本,不安装依赖。以下命令在 Linux、Hugo 0.164.0、Python 3.11.4 下验证,适用于 bash/zsh。重复实验时换一个新目录名;后续命令都在 hugo-stale-demo 内运行,不能在真实站点根目录复制执行初始化代码。
- 创建最小配置、模板和一篇临时文章:
hugo version
python3 --version
mkdir hugo-stale-demo
cd hugo-stale-demo
mkdir -p content layouts/_default static
cat > hugo.toml <<'TOML'
baseURL = 'https://example.org/'
title = 'Stale output demo'
disableKinds = ['taxonomy', 'term', 'RSS', 'sitemap']
TOML
cat > layouts/_default/single.html <<'HTML'
<!doctype html><html><head><title>{{ .Title }}</title></head>
<body><h1>{{ .Title }}</h1>{{ .Content }}</body></html>
HTML
cat > layouts/_default/list.html <<'HTML'
<!doctype html><html><head><title>{{ .Title }}</title></head>
<body>{{ range .Pages }}<a href="{{ .RelPermalink }}">{{ .Title }}</a>{{ end }}</body></html>
HTML
cat > content/old.md <<'MARKDOWN'
+++
title = 'Old page'
+++
Only a disposable demo page.
MARKDOWN
这里保留一个空 static 目录,以兼容本文测试版本的清理行为。模板只用来生成可核对的文件,没有引入主题、网络资源或真实站点配置。
3. 复现与修复:删除源文件并不等于删除产物
- 构建一次,只删除刚创建的演示文章,再构建到相同目录:
hugo --quiet --destination out-existing
test -f out-existing/old/index.html
python3 - <<'PY_DELETE'
from pathlib import Path
Path("content/old.md").unlink()
PY_DELETE
hugo --quiet --destination out-existing
test -f out-existing/old/index.html && printf 'STALE: old/index.html\n'
应看到 STALE: old/index.html。这证明残留发生在本地磁盘,尚未涉及浏览器或 CDN。演示站没有 404 模板时可能出现缺少布局的警告;本例只核对首页与文章页。
- 复制输出,在副本上测试清理。
out-cleaned必须不存在,copytree会拒绝覆盖已有目录:
python3 - <<'PY_COPY'
import shutil
shutil.copytree("out-existing", "out-cleaned")
PY_COPY
hugo --quiet --cleanDestinationDir --destination out-cleaned
test ! -f out-cleaned/old/index.html && printf 'CLEAN: old/index.html absent\n'
应看到 CLEAN: old/index.html absent,原来的 out-existing 仍保留旧页。Hugo 命令参考列出了 --destination 和 --cleanDestinationDir;后者可能删除目标里手工放入的文件,不要把它当成只删旧文章的安全过滤器。不同版本的清理细节有差异,先在副本上验证。
4. 实现:只读比较 HTML 清单
将以下代码保存为当前目录的 audit_output.py:
"""Compare HTML path inventories, without modifying either tree. Python 3.10+."""
import argparse
import json
import os
from pathlib import Path
import stat
import sys


def scan_error(error):
    raise error


def html_paths(root):
    result = set()
    for folder, dirs, files in os.walk(root, onerror=scan_error, followlinks=False):
        for name in dirs + files:
            if (Path(folder) / name).is_symlink():
                raise ValueError(f"symbolic link not allowed: {Path(folder) / name}")
        for name in files:
            path = Path(folder) / name
            if path.suffix.lower() != ".html":
                continue
            if not stat.S_ISREG(path.stat().st_mode):
                raise ValueError(f"not a regular HTML file: {path}")
            result.add(path.relative_to(root).as_posix())
    return result


def directory(value):
    path = Path(value)
    if path.is_symlink():
        raise ValueError(f"symbolic link not allowed: {path}")
    path = path.resolve(strict=True)
    if not path.is_dir():
        raise ValueError(f"not a directory: {path}")
    return path


def main():
    parser = argparse.ArgumentParser(description=__doc__)
    parser.add_argument("--existing", required=True)
    parser.add_argument("--fresh", required=True)
    args = parser.parse_args()
    try:
        existing = directory(args.existing)
        fresh = directory(args.fresh)
        if existing == fresh or existing in fresh.parents or fresh in existing.parents:
            raise ValueError("directories must be separate and non-nested")
        old_paths, new_paths = html_paths(existing), html_paths(fresh)
        if not new_paths:
            raise ValueError("fresh build has no HTML files")
        extra = sorted(old_paths - new_paths)
        missing = sorted(new_paths - old_paths)
        print(json.dumps({"extra_html": extra, "missing_html": missing},
                         ensure_ascii=True, sort_keys=True))
        return 1 if extra or missing else 0
    except (OSError, ValueError) as error:
        print(f"ERROR: {error}", file=sys.stderr)
        return 2


if __name__ == "__main__":
    raise SystemExit(main())
检查只比较相对路径,不比较文件内容、大小或修改时间。extra_html 表示已有目录比参考构建多出的 HTML 候选,missing_html 表示参考构建中有而已有目录里没有的 HTML。两个同名文件即使内容不同,也不会被这个工具发现。
根据 os.walk 官方说明,目录扫描错误默认可能被忽略。这里通过 onerror 让失败中止,并拒绝扫描树内的符号链接;不把漏扫目录当成检查通过。工具只用于可信、检查期间不变化的本地目录,不提供对恶意路径或并发替换的安全保证。
5. 验证:用退出码区分残留与扫描失败
- 查看参数,然后比较原输出和清理后的副本:
python3 audit_output.py --help
if python3 audit_output.py --existing out-existing --fresh out-cleaned; then
    status=0
else
    status=$?
fi
printf 'exit=%s\n' "$status"
预期结果如下,--help 的帮助文本除外:
{"extra_html": ["old/index.html"], "missing_html": []}
exit=1
- 退出码约定如下。脚本发生扫描错误时只向标准错误写诊断,不输出成功 JSON:
| 退出码 | 含义 |
|---|---|
0 |
两边的 HTML 路径集合一致。 |
1 |
存在多余或缺失的 HTML 路径,需要审查。 |
2 |
参数错误、目录不存在、目录重叠、符号链接、空参考清单或扫描失败。 |
这不是自动删除清单。手工添加到输出目录的 HTML、旧版合法页面、不同配置生成的页面,也会成为差异候选;先核实用途和发布策略。
6. 自动化:每次使用全新的参考目录
将以下代码保存为 preview_check.py,与 audit_output.py 放在一起。它在当前项目根目录调用 Hugo,既不清空也不重建 --existing 指定的目录:
"""Build into a fresh temporary directory, then audit an existing output."""
import argparse
from pathlib import Path
import subprocess
import sys
from tempfile import TemporaryDirectory

parser = argparse.ArgumentParser(description=__doc__)
parser.add_argument("--existing", default="public")
parser.add_argument("--config", default="hugo.toml")
args = parser.parse_args()

workspace = Path("/tmp/codex-work")
workspace.mkdir(parents=True, exist_ok=True)
with TemporaryDirectory(prefix="hugo-output-", dir=workspace) as temporary:
    preview = Path(temporary) / "site"
    subprocess.run(
        ["hugo", "--quiet", "--config", args.config,
         "--destination", str(preview)],
        check=True, timeout=120,
    )
    result = subprocess.run(
        [sys.executable, "audit_output.py", "--existing", args.existing,
         "--fresh", str(preview)],
        check=False, timeout=120,
    )
    raise SystemExit(result.returncode)
- 在演示站运行:
python3 preview_check.py --existing out-cleaned
if python3 preview_check.py --existing out-existing; then
    status=0
else
    status=$?
fi
printf 'exit=%s\n' "$status"
第一次应输出两个空列表并返回 0;第二次应报告 old/index.html 并打印 exit=1。TemporaryDirectory在上下文退出时清理本次参考目录;构建失败或超时也不会继续比较,已有目录保持不变。强制杀死进程或断电时不能依赖自动清理。
- 用于自己的项目时,将这两个 Python 文件放在项目根目录,再显式指定实际配置,例如
python3 preview_check.py --config hugotest.toml --existing public。参考构建必须使用相同的源文件、语言、配置、环境变量和构建选项;不要一边构建一边扫描。构建较慢时按需要调整timeout=120,不要去掉check=True。
通过差异审查以后,还要用站内链接与图片检查检查页面引用,用 sitemap 检查核对当前发布清单。部署端是否移除了旧路径,要另行通过 HTTP 验证;本地通过不等于线上旧页已经消失。
7. 排障:按差异来源处理
| 现象 | 直接处理 |
|---|---|
extra_html 非空 |
检查对应源文件是否删除、改 URL 或变成草稿;确认是否属于手工维护页面,再决定单独移除还是部署完整新目录。 |
missing_html 非空 |
确认比较方向、构建配置和发布步骤;不能只把这些项当成缓存问题。 |
symbolic link not allowed |
使用独立、真实目录中的构建产物,不要为绕过检查而自动跟随链接。 |
fresh build has no HTML files |
检查模板、内容资格和目标路径;空参考不能证明已有文件全都该删。 |
| 本地旧页已消失,HTTP 仍返回旧正文 | 先核对服务器实际服务目录与响应正文,再检查部署遗漏、代理或 CDN 缓存;不要仅凭状态码判断。 |
检查器只扫描 .html 后缀,大小写不敏感;不会检查图片、XML、CSS、JSON 或服务器重写。它将路径保存在集合中,适合中小型静态站点,也不验证输出内容正确性。
8. 总结
先在本地确认旧 HTML 是否残留,再用全新构建作为参考,能把“缓存没刷新”和“部署还留着旧文件”分开。让差异检查只读、错误返回非零,并在审查后另行部署。不要因为一次构建成功,就认为旧路径已经下线。
- 原文作者:春江暮客
- 原文链接:https://www.bobobk.com/hugo-stale-public-files-python.html
- 版权声明:本作品采用 知识共享署名-非商业性使用-禁止演绎 4.0 国际许可协议 进行许可,非商业转载请注明出处(作者,原文链接),商业转载请联系作者获得授权。