Python SQLite UPSERT vs REPLACE: Keep Related Records When Updating
On this page
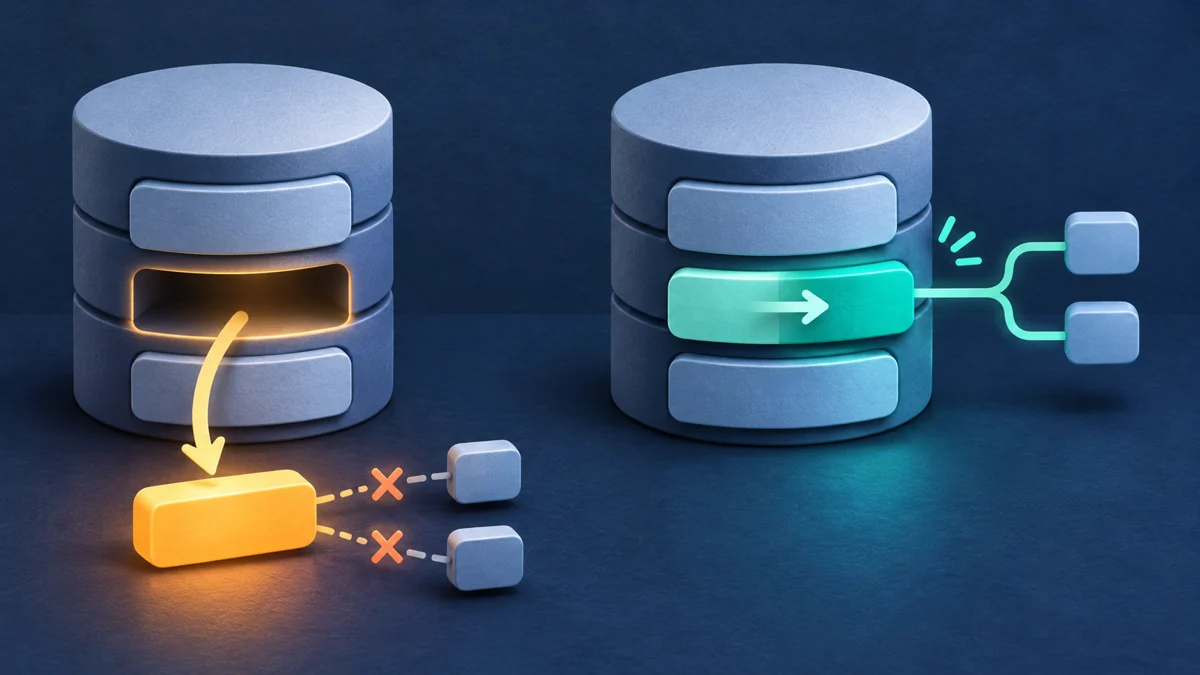
A scheduled job updates a status with INSERT OR REPLACE. The command succeeds, yet related report records disappear. On a uniqueness conflict, SQLite REPLACE deletes the existing row before inserting another; it is not an UPDATE of selected fields. SQLite conflict handling
This beginner-to-intermediate tutorial reproduces the problem in an in-memory database, switches to UPSERT, and checks related records, creation dates, and error rollback with Python’s standard library. The demo accepts no database path and never opens an existing database.
1. Method: update by unique key without replacing the row
jobs.nameis the primary key; each job has a status and creation date.results.job_namereferences a job. The demo deliberately declaresON DELETE CASCADE: deleting the parent also deletes its children. This is the declared foreign-key action, not Python losing data. SQLite foreign-key actions- UPSERT handles a name conflict with
ON CONFLICT(name) DO UPDATE, changing onlystatus. The omittedcreated_atstays unchanged; a new name still inserts normally.
excluded.status is the status proposed for insertion. The conflict target must match a primary key, UNIQUE constraint, or suitable unique index. UPSERT does not suppress NOT NULL or foreign-key errors. SQLite UPSERT documentation
If you have not verified enforcement, start with SQLite foreign-key checks and batch rollback. Do not disable foreign keys to make REPLACE appear to work.
2. Setup: check the SQLite library Python actually uses
Use Python 3.11+ with SQLite 3.24.0+, without pip packages or a separate database service. Tested on Linux with Python 3.11.4 and SQLite 3.41.2. The SQLite minimum is the version that introduced UPSERT, not an inference from the Python version. UPSERT version history
Run these commands in order in one terminal. Choose a fresh directory name when repeating the experiment:
python3 --version
python3 -c 'import sqlite3; print(sqlite3.sqlite_version)'
mkdir sqlite-upsert-demo
cd sqlite-upsert-demo
Save the next section as upsert_demo.py, or download the complete demo script. The default mode is upsert; replace is only an in-memory comparison.
3. Complete implementation: preserve relationships and creation dates
"""Compare REPLACE and UPSERT in a fresh in-memory database. Python 3.11+."""
import argparse
from contextlib import closing
import json
import sqlite3
import sys


STATEMENTS = {
    "replace": """INSERT OR REPLACE INTO jobs(name, status, created_at)
                  VALUES (?, ?, ?)""",
    "upsert": """INSERT INTO jobs(name, status, created_at) VALUES (?, ?, ?)
                 ON CONFLICT(name) DO UPDATE SET status = excluded.status""",
}


def open_demo():
    if sqlite3.sqlite_version_info < (3, 24, 0):
        raise RuntimeError("SQLite 3.24.0+ is required")
    options = {"isolation_level": None}
    if sys.version_info >= (3, 12):
        options["autocommit"] = True
    con = sqlite3.connect(":memory:", **options)
    try:
        con.execute("PRAGMA foreign_keys = ON")
        if con.execute("PRAGMA foreign_keys").fetchone() != (1,):
            raise RuntimeError("foreign keys are not enabled")
        con.execute("""CREATE TABLE jobs (
            name TEXT PRIMARY KEY NOT NULL,
            status TEXT NOT NULL,
            created_at TEXT NOT NULL
        )""")
        con.execute("""CREATE TABLE results (
            id INTEGER PRIMARY KEY,
            job_name TEXT NOT NULL REFERENCES jobs(name) ON DELETE CASCADE,
            value TEXT NOT NULL
        )""")
        con.execute("INSERT INTO jobs VALUES (?, ?, ?)",
                    ("nightly", "queued", "2026-01-01"))
        con.execute("INSERT INTO results VALUES (?, ?, ?)",
                    (1, "nightly", "report.csv"))
        return con
    except Exception:
        con.close()
        raise


def write_job(con, mode, name, status, created_at):
    statement = STATEMENTS[mode]
    con.execute("BEGIN")
    try:
        con.execute(statement, (name, status, created_at))
        con.execute("COMMIT")
    except Exception:
        if con.in_transaction:
            con.execute("ROLLBACK")
        raise


def snapshot(con):
    return {
        "jobs": [list(row) for row in con.execute(
            "SELECT name, status, created_at FROM jobs ORDER BY name")],
        "results": [list(row) for row in con.execute(
            "SELECT id, job_name, value FROM results ORDER BY id")],
    }


def main():
    parser = argparse.ArgumentParser(description=__doc__, allow_abbrev=False)
    parser.add_argument("--mode", choices=STATEMENTS, default="upsert")
    args = parser.parse_args()
    try:
        with closing(open_demo()) as con:
            before = snapshot(con)
            write_job(con, args.mode, "nightly", "done", "2026-02-01")
            result = {"mode": args.mode, "before": before, "after": snapshot(con)}
        print(json.dumps(result, ensure_ascii=True, sort_keys=True))
        return 0
    except (sqlite3.Error, RuntimeError) as exc:
        print(f"ERROR: {exc}", file=sys.stderr)
        return 1


if __name__ == "__main__":
    sys.exit(main())
The connection uses isolation_level=None on Python 3.11; on 3.12+ it also passes autocommit=True explicitly. SQL BEGIN, COMMIT, and ROLLBACK control this write in both cases. Do not mix this connection strategy into a connection with an existing transaction. See Python 3.11 transaction control and the current autocommit reference.
All values use ? parameter binding; SQL structure comes only from a fixed statement map. closing() closes the connection on exit. Foreign-key enforcement is enabled and checked before transactions. This example updates a non-key field, not parent keys or their cascade policies.
4. Compare runs: successful exit does not prove preservation
python3 upsert_demo.py --help
python3 upsert_demo.py --mode replace
python3 upsert_demo.py --mode upsert
Each run creates its own identical fresh database and should exit 0. The output is one JSON line; compare after:
| Mode | status | created_at | results |
|---|---|---|---|
| replace | done | 2026-02-01 | Empty array |
| upsert | done | 2026-01-01 | Original report.csv record |
REPLACE can succeed completely while violating the business requirement to retain reports. PRAGMA foreign_key_check will not flag this cascade deletion either: the resulting database has no orphan rows. Validate expected data, not just exit status or constraints.
5. Automated checks: insertion, repeat updates, and error rollback
Save this as test_upsert.py, or download the complete test script, beside the demo:
"""Run beside upsert_demo.py; all databases are disposable and in-memory."""
from contextlib import closing
import json
from pathlib import Path
import sqlite3
import subprocess
import sys
from upsert_demo import open_demo, snapshot, write_job

script = Path(__file__).with_name("upsert_demo.py")
for mode in ("replace", "upsert"):
    run = subprocess.run([sys.executable, str(script), "--mode", mode],
                         text=True, capture_output=True, check=True)
    assert run.stderr == ""
    report = json.loads(run.stdout)
    assert report["before"]["results"] == [[1, "nightly", "report.csv"]]
    after = report["after"]
    assert after["jobs"][0][:2] == ["nightly", "done"]
    if mode == "replace":
        assert after["results"] == []
        assert after["jobs"][0][2] == "2026-02-01"
    else:
        assert after["results"] == report["before"]["results"]
        assert after["jobs"][0][2] == "2026-01-01"

with closing(open_demo()) as con:
    # New key inserts, the same key updates only the requested field.
    name = "daily'中文"
    write_job(con, "upsert", name, "queued", "2026-03-01")
    write_job(con, "upsert", name, "done", "2099-01-01")
    write_job(con, "upsert", "nightly", "done", "2099-01-01")
    write_job(con, "upsert", "nightly", "done", "2099-01-01")
    before = snapshot(con)
    assert before["jobs"] == [
        [name, "done", "2026-03-01"],
        ["nightly", "done", "2026-01-01"],
    ]
    assert before["results"] == [[1, "nightly", "report.csv"]]
    try:
        write_job(con, "upsert", "nightly", None, "2099-01-01")
    except sqlite3.IntegrityError:
        pass
    else:
        raise AssertionError("NOT NULL failure was expected")
    assert snapshot(con) == before
    assert not con.in_transaction
    assert con.execute("PRAGMA foreign_key_check").fetchall() == []

for args, expected in [(["--help"], 0), (["--mode", "unknown"], 2)]:
    run = subprocess.run([sys.executable, str(script), *args], capture_output=True)
    assert run.returncode == expected
print("PASS: REPLACE loss, UPSERT preservation, insert, repeat, rollback, CLI")
python3 test_upsert.py
Expected output:
PASS: REPLACE loss, UPSERT preservation, insert, repeat, rollback, CLI
The test checks preserved children and creation dates on updates, new-key insertion, repeated execution, quoted and Chinese names, and an unchanged database with a closed transaction after NOT NULL failure. It does not test concurrent writers or disk faults. Both modes use memory only, so no database files need cleanup.
6. Troubleshooting and integration
| Symptom | Check and action |
|---|---|
near "ON": syntax error |
Print sqlite3.sqlite_version and check UPSERT support in the actual library, not just the system sqlite3 executable. |
| Conflict target does not match a constraint | Inspect the table definition and unique indexes. Match composite unique keys to the actual design; do not add constraints to dirty data blindly. |
NOT NULL constraint failed |
Fix the input and keep the failure status. UPSERT does not turn missing values into valid ones. |
| Child records still disappear | Inspect the SQL actually executed, other deletes, and triggers. This demo proves only the shown schema and statements. |
database is locked |
Use the SQLite lock contention and short-transaction tutorial to investigate overlapping writes. UPSERT does not increase write concurrency. |
Before changing a real database, make a SQLite backup and verify restoration, then check its schema, triggers, and business assertions on a copy. Reverting the SQL to REPLACE restores the old behavior, not already deleted child records; recover lost data from a verified backup or another reliable source.
7. Summary
Use an explicit UPSERT update list when changing selected fields by unique key; do not treat REPLACE as shorthand for UPDATE. Assert parent fields and child records, then test rollback after errors. After the memory experiment passes, validate the real schema and job workflow on a backup copy.
- Author: yanzhi
- Original article: https://www.bobobk.com/en/python-sqlite-upsert-not-replace.html
- License: This work is licensed under CC BY-NC-ND 4.0. See the license for attribution, noncommercial use and no-derivatives terms.
Related articles
- Fix Python SQLite Foreign Keys: Connection Checks, Batch Rollback, and Orphan Audits
- Fix Python SQLite database is locked: Timeouts and Short Transactions
- Python Timeout Leaves Workers Running? Stop a Linux Process Group
- Linux File Size vs Disk Usage: Inspect Sparse Files with Python
- Measure Python Task Duration: Wall Time vs CPU Time with perf_counter and process_time