Compare CSV Snapshots by ID with Python: Added, Removed, and Changed Records
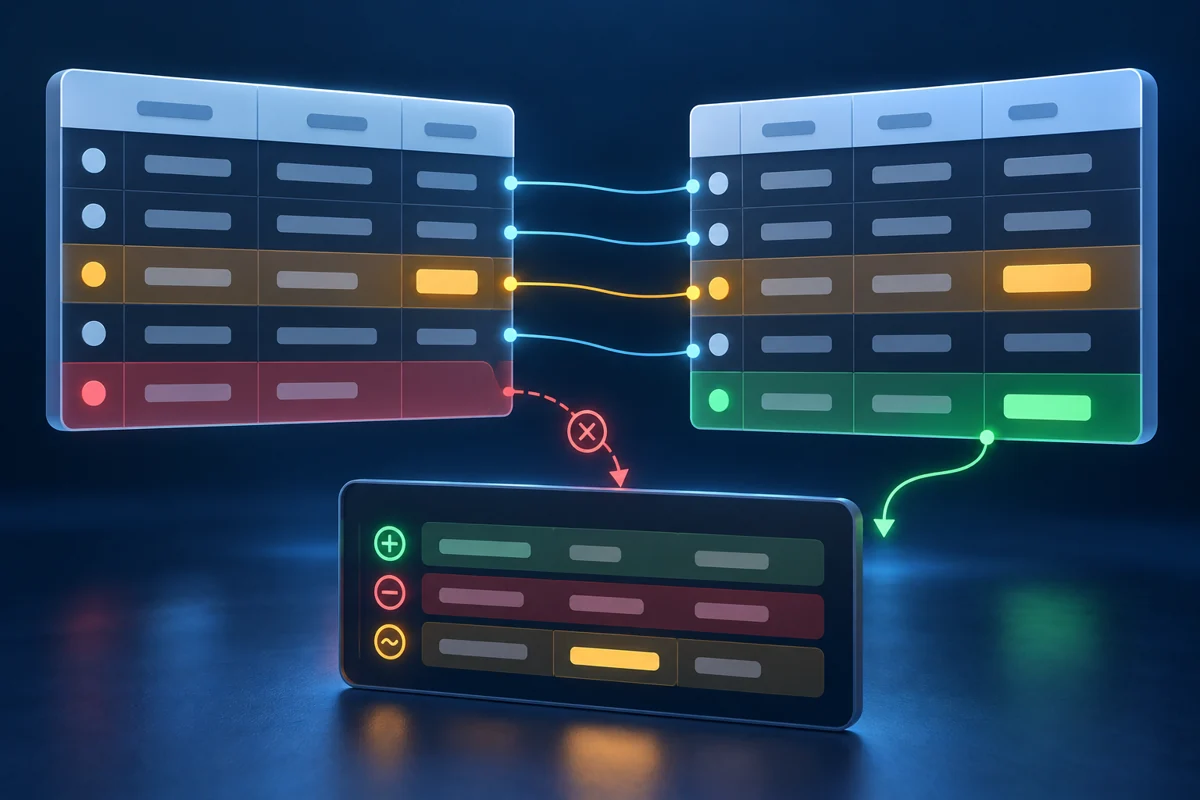
Two daily CSV exports can have the same row count while containing different data. A plain text diff can also turn a row reorder into a large, distracting change.
This beginner-to-intermediate tutorial builds a standard-library Python command that aligns records by a unique ID and reports added IDs, removed IDs, and changed fields. Exit codes distinguish equal snapshots, real changes, and failed checks. Use it for configuration tables, sample lists, and daily exports that comfortably fit together in memory.
1. Method: define the comparison rules
- Both files use comma-separated UTF-8 CSV, optionally starting with a BOM. Column names and order must match. Column names must be nonempty, unique, and free of surrounding whitespace.
- The default unique key is
sample_id; change it with--key. Empty, padded, or duplicate keys are rejected so dictionary insertion cannot silently overwrite a record. - Data row order is ignored. Parsed field values are compared as exact strings:
001and1are different IDs;1and1.0are different values. Whitespace and embedded newlines in ordinary fields remain significant. - Header-only files are valid; completely empty files are invalid. Renaming a key produces a removal and an addition. Composite keys and numeric tolerances are outside this example.
A separate CSV structure check helps distinguish column-format problems from data changes. Larger inputs need a disk index or external sorting. This implementation holds both datasets and the report in memory, so memory use grows with the input and changes.
2. Setup and two snapshots
Use Python 3.9 or newer, without pip packages. The examples were tested on Linux with Python 3.11.4; shell commands work in Bash or zsh.
- Create a demo directory and run subsequent commands there. Choose another directory name when repeating the exercise to avoid overwriting files:
python3 --version
mkdir csv-diff-demo
cd csv-diff-demo
- Create two small files. The new snapshot reorders rows, changes the label for
001, removes002, and adds004:
cat > old.csv <<'CSV'
sample_id,label,note
001,0,stable
002,1,removed
003,1,keep
CSV
cat > new.csv <<'CSV'
sample_id,label,note
003,1,keep
001,1,stable
004,0,added
CSV
- Save the next section as
compare_csv.py, or download the complete script. Use a separate report path: shell>truncates its destination before Python starts, so never redirect to either input file.
3. Implementation: index and compare by key
"""Compare two CSV snapshots by one unique key. Python 3.9+, standard library."""
import argparse
import csv
import json
from pathlib import Path
import sys


def load_csv(path, key):
    records = {}
    with open(path, encoding="utf-8-sig", newline="") as handle:
        reader = csv.reader(handle, strict=True)
        header = next(reader, None)
        if not header or any(not name or name != name.strip() for name in header):
            raise ValueError(f"{path}: empty or padded column name")
        if len(set(header)) != len(header) or key not in header:
            raise ValueError(f"{path}: columns must be unique and include {key!r}")
        key_index = header.index(key)
        for number, row in enumerate(reader, 1):
            if len(row) != len(header):
                raise ValueError(f"{path}: record {number}: wrong field count")
            identity = row[key_index]
            if not identity or identity != identity.strip():
                raise ValueError(f"{path}: record {number}: empty or padded key")
            if identity in records:
                raise ValueError(f"{path}: record {number}: duplicate key {identity!r}")
            records[identity] = dict(zip(header, row))
    return header, records


def compare(old_path, new_path, key):
    old_header, old = load_csv(old_path, key)
    new_header, new = load_csv(new_path, key)
    if old_header != new_header:
        raise ValueError("headers differ: column names and order must match")
    added = sorted(new.keys() - old.keys())
    removed = sorted(old.keys() - new.keys())
    changed = []
    for identity in sorted(old.keys() & new.keys()):
        fields = {
            name: {"old": old[identity][name], "new": new[identity][name]}
            for name in old_header
            if old[identity][name] != new[identity][name]
        }
        if fields:
            changed.append({"id": identity, "fields": fields})
    return {"key": key, "added": added, "removed": removed, "changed": changed}


def main():
    parser = argparse.ArgumentParser(description=__doc__)
    parser.add_argument("old", type=Path)
    parser.add_argument("new", type=Path)
    parser.add_argument("--key", default="sample_id", help="unique key column")
    args = parser.parse_args()
    try:
        report = compare(args.old, args.new, args.key)
        json.dump(report, sys.stdout, ensure_ascii=True, indent=2)
        sys.stdout.write("\n")
        sys.stdout.flush()
    except (OSError, UnicodeError, ValueError, csv.Error) as exc:
        parser.exit(2, f"error: {exc}\n")
    return int(any(report[name] for name in ("added", "removed", "changed")))


if __name__ == "__main__":
    sys.exit(main())
The script uses csv.reader for quotes, commas, and multiline fields, then explicitly checks headers, field counts, and key uniqueness before constructing dictionaries. strict=True covers malformed input recognized by the parser, not all business rules. See Python’s official CSV documentation for newline="". Record numbers start after the header and are not physical line numbers.
The added, removed, and changed lists are sorted by ID string for repeatable review. Additions and removals contain IDs only; changes contain old and new values for affected fields. The report’s id always contains the selected key’s value, even when you choose another key column name. Standard-library json.dump produces the report; escaped non-ASCII characters decode without losing their values.
JSON output begins only after both inputs pass validation. A report write failure can still leave partial output, so inspect the exit code. The script does not save reports atomically or lock inputs that another process is changing. Use stable snapshots from completed exports.
4. Run and inspect the result
python3 compare_csv.py --help
if python3 compare_csv.py old.csv new.csv --key sample_id > diff.json; then
  result=0
else
  result=$?
fi
printf 'exit=%s\n' "$result"
cat diff.json
Expect exit=1: the comparison completed successfully and found changes. JSON formatting may differ from this compact presentation, but its data should be:
{
  "key": "sample_id",
  "added": ["004"],
  "removed": ["002"],
  "changed": [
    {"id": "001", "fields": {"label": {"old": "0", "new": "1"}}}
  ]
}
003 is absent from the report because only its position changed. The exit codes below are this script’s interface; see the official sys.exit documentation for integer exit statuses.
| Exit code | Meaning | Next action |
|---|---|---|
| 0 | Both inputs are valid and equal by key | Continue the unchanged-data workflow |
| 1 | Both inputs are valid, with additions, removals, or modifications | Review the report before accepting changes |
| 2 | Argument, input, or processing I/O error | Fix the error, rerun, and disregard this report |
5. Validate changes, row order, and bad input
Save this as check_diff.py and run python3 check_diff.py. It checks the demo report and confirms that row reordering or a BOM does not count as a change, while a duplicate key returns 2 without JSON output:
import csv
import json
import subprocess
import sys

with open("diff.json", encoding="utf-8") as handle:
    report = json.load(handle)
assert report == {
    "key": "sample_id",
    "added": ["004"],
    "removed": ["002"],
    "changed": [{"id": "001", "fields": {"label": {"old": "0", "new": "1"}}}],
}
with open("old.csv", encoding="utf-8", newline="") as handle:
    rows = list(csv.reader(handle))
with open("reordered.csv", "w", encoding="utf-8-sig", newline="") as handle:
    writer = csv.writer(handle)
    writer.writerow(rows[0])
    writer.writerows(reversed(rows[1:]))
result = subprocess.run(
    [sys.executable, "compare_csv.py", "old.csv", "reordered.csv"],
    text=True, capture_output=True, check=False,
)
assert result.returncode == 0, result.stderr
assert json.loads(result.stdout) == {
    "key": "sample_id", "added": [], "removed": [], "changed": [],
}
with open("duplicate.csv", "w", encoding="utf-8", newline="") as handle:
    csv.writer(handle).writerows([rows[0], rows[1], rows[1]])
result = subprocess.run(
    [sys.executable, "compare_csv.py", "old.csv", "duplicate.csv"],
    text=True, capture_output=True, check=False,
)
assert result.returncode == 2
assert "duplicate key" in result.stderr
assert result.stdout == ""
print("PASS: changes, row order, BOM, and duplicate rejection")
Expect PASS: changes, row order, BOM, and duplicate rejection. The check creates files in the demo directory and leaves both original snapshots intact.
6. Automation and troubleshooting
In scheduled jobs or CI, set -e would also stop on exit code 1. Capture the status with if and handle it explicitly. Save the following as check_snapshot.sh and run bash check_snapshot.sh:
#!/usr/bin/env bash
set -eu
if python3 compare_csv.py old.csv new.csv --key sample_id > diff.json; then
  echo "No record changes"
else
  result=$?
  case "$result" in
    1) echo "Records changed; review diff.json" >&2 ;;
    *) echo "Comparison failed; do not use diff.json" >&2 ;;
  esac
  exit "$result"
fi
This wrapper preserves exit code 1 for changes so a workflow requiring review can pause. It does not automatically approve changes. On a failed comparison, an existing diff.json must also be disregarded.
| Problem | Action |
|---|---|
duplicate key |
Inspect source records; use the duplicate ID checker first if useful. Do not arbitrarily keep the last row. |
headers differ |
Check column names and order, then re-export to an agreed schema. |
wrong field count or CSV error |
Inspect delimiters, quotes, and commas inside fields; the script does not guess the format. |
| Encoding error | Follow the CSV encoding troubleshooting guide, identify the source encoding, and convert strictly to UTF-8. |
| Oversized field rejected | Investigate the input before deliberately adjusting csv.field_size_limit. |
| Memory exhaustion or a process killed by the system | Reduce the input size or switch to a disk index. Report-file existence alone does not prove success. |
7. Summary
Aligning records by a stable unique ID separates row-order changes from data changes. Validate inputs, check the exit code, then review added IDs, removed IDs, and modified fields. This in-memory script suits small to medium snapshots; use a disk index when the data outgrows available memory.
- 原文作者:春江暮客
- 原文链接:https://www.bobobk.com/en/python-csv-diff-by-key.html
- 版权声明:本作品采用 知识共享署名-非商业性使用-禁止演绎 4.0 国际许可协议 进行许可,非商业转载请注明出处(作者,原文链接),商业转载请联系作者获得授权。
相关文章
- Validate CSV Structure with Python: Exact Headers, Column Order, and Field Counts
- Split Large CSV Files with Python: Headers, Multiline Fields, and Completion Checks
- Read CSV Files Inside tar.gz with Python: Summaries Without Extraction
- Validate JSONL with Python: Find Broken Lines and Duplicate Keys
- Fix Linux Argument list too long with find and Python