Merge Sorted Logs by Timestamp in Python with heapq.merge
On this page
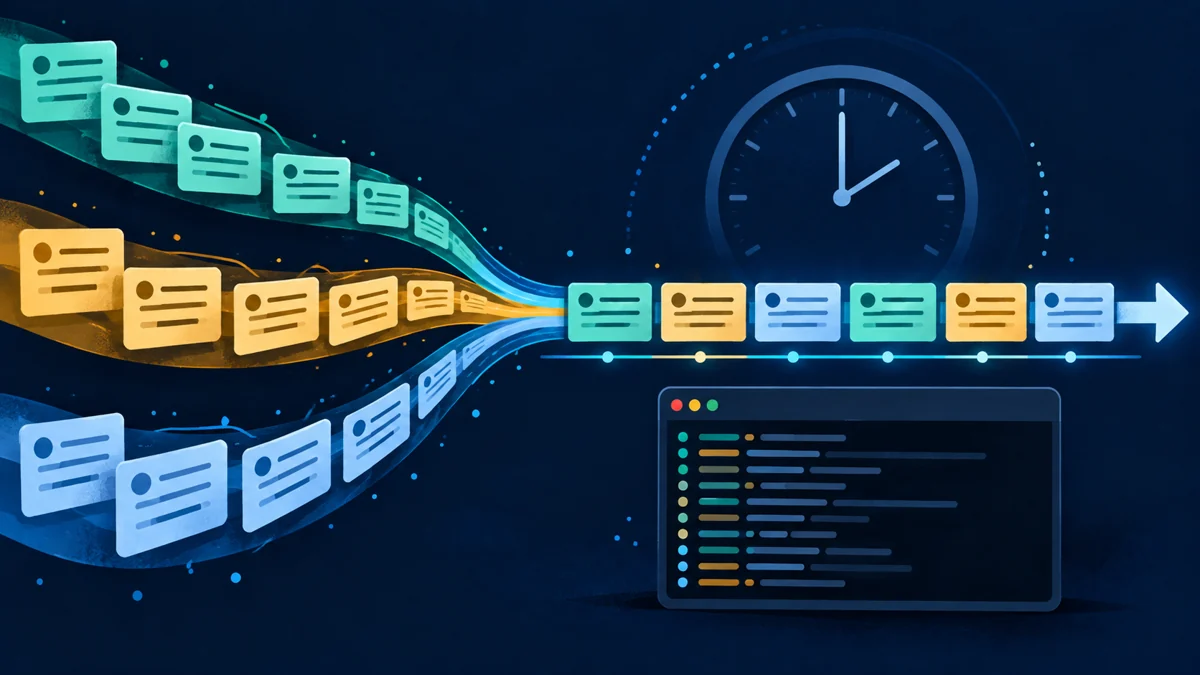
Each worker writes its own chronological log, but concatenating files with cat scrambles the combined timeline. Loading all lines into a list before sorting can also consume substantial memory. This beginner-to-intermediate tutorial uses the standard-library heapq.merge to merge sorted logs into JSONL with UTC timestamps, source paths, and line numbers.
Use completed, ordinary UTF-8 files that remain unchanged while being read. Each line must contain a timestamp, one space, and a nonempty message; timestamps contain no spaces, for example 2026-10-28T08:00:00+08:00 task started. Convert multiline stack traces to single-line events first. For the end of just one log, start with the deque log-tail tutorial.
1. Method: normalize instants, then merge sorted inputs
- Parse timestamps with
Zor an explicit UTC offset and convert to UTC, rather than sorting raw strings. - Check that each file is nondecreasing by time. Reject backwards timestamps; equal timestamps are allowed.
- Merge records into a temporary file. Create a new output only after every input has been read and validated.
The official heapq.merge documentation describes an iterator that expects sorted inputs without loading every record at once. It does not sort an unsorted input for you. This tool breaks equal-time ties by command-line file order, then original line number. It keeps duplicates and does not infer causality.
Only a small set of candidate records is retained, but a single line can still be large; there is no fixed byte-level memory limit. Temporary storage must hold the entire JSONL, with additional space needed during the final copy. The tool accepts at most 64 inputs and holds them open together; your operating-system limit can be lower.
2. Setup: create two repeatable logs
Use Python 3.11 or newer with no third-party packages. Examples were tested on Linux with Python 3.11.4; shell commands work in bash and zsh. Use a new writable directory and stay there for subsequent steps. Choose another directory name when repeating the experiment.
- Create sorted inputs with deliberately different UTC offsets:
python3 --version
mkdir merge-logs-demo
cd merge-logs-demo
cat > worker-a.log <<'EOF'
2026-10-28T08:00:00+08:00 alpha started
2026-10-28T08:00:02+08:00 alpha finished
EOF
cat > worker-b.log <<'EOF'
2026-10-28T00:00:00Z beta started
2026-10-28T00:00:01Z beta finished
EOF
- Save the next section as
merge_logs.py.
Python 3.11’s datetime.fromisoformat() accepts the sample Z timestamps. Converting aware values to UTC avoids sorting 08:00 Beijing time after the equivalent UTC 00:00. Records without a timezone are rejected. For daily reports, continue with zoneinfo log-date aggregation.
3. Implementation: create output after validation
"""Merge completed, sorted UTF-8 logs into new JSONL output. Python 3.11+."""
import argparse
from contextlib import ExitStack
from datetime import datetime, timezone
import heapq
import json
from pathlib import Path
import shutil
import sys
import tempfile


def records(source, path, index):
    previous = None
    for number, raw in enumerate(source, 1):
        text = raw.rstrip("\n")
        stamp, separator, message = text.partition(" ")
        try:
            if not separator or not message:
                raise ValueError("expected TIMESTAMP message")
            instant = datetime.fromisoformat(stamp)
            if instant.tzinfo is None or instant.utcoffset() is None:
                raise ValueError("timestamp needs Z or a UTC offset")
            instant = instant.astimezone(timezone.utc)
            if previous is not None and instant < previous:
                raise ValueError("timestamps go backwards")
        except (ValueError, OverflowError) as exc:
            raise ValueError(f"{path}:{number}: {exc}") from exc
        previous = instant
        yield instant, index, number, message


def merge_logs(paths, output):
    if not 1 <= len(paths) <= 64:
        raise ValueError("provide 1..64 input files")
    resolved = [path.resolve() for path in paths]
    if len(set(resolved)) != len(resolved):
        raise ValueError("input paths must be distinct")
    if output.resolve() in resolved:
        raise ValueError("output must differ from every input")
    count = 0
    with ExitStack() as stack:
        streams = []
        for index, path in enumerate(paths):
            source = stack.enter_context(path.open(encoding="utf-8", errors="strict"))
            streams.append(records(source, path, index))
        with tempfile.TemporaryFile(
            mode="w+", encoding="utf-8", newline="\n", dir=output.parent
        ) as scratch:
            for instant, index, number, message in heapq.merge(*streams):
                row = {"time": instant.isoformat(), "source": str(paths[index]),
                       "line": number, "message": message}
                scratch.write(json.dumps(row, ensure_ascii=False) + "\n")
                count += 1
            scratch.seek(0)
            created = False
            try:
                with output.open("x", encoding="utf-8", newline="\n") as target:
                    created = True
                    shutil.copyfileobj(scratch, target)
            except BaseException:
                if created:
                    output.unlink()
                raise
    return count


def main():
    parser = argparse.ArgumentParser(description=__doc__, allow_abbrev=False)
    parser.add_argument("inputs", nargs="+", type=Path)
    parser.add_argument("-o", "--output", type=Path, required=True)
    args = parser.parse_args()
    try:
        count = merge_logs(args.inputs, args.output)
    except (OSError, UnicodeError, ValueError) as exc:
        print(f"ERROR: {exc}", file=sys.stderr)
        return 2
    print(json.dumps({"records": count, "output": str(args.output)}))
    return 0


if __name__ == "__main__":
    raise SystemExit(main())
The official ExitStack examples show how to manage a variable number of context resources. Previously opened inputs close even if opening a later file fails. The temporary file is placed in the output directory and cleaned up when its context closes. The output parent directory must already exist.
Exclusive x mode rejects existing files, symlinks, and input paths instead of overwriting results. Handled read or format failures occur before output creation; an exception during copying triggers an attempt to remove the output created by this run. The final copy is not atomic publication. Other processes must wait for exit status 0; forced termination or power loss can leave a partial file. Use trusted local directories without concurrent path replacement.
4. Usage: verify order and source locations
- Inspect help, merge, and assert the result:
python3 merge_logs.py --help
python3 merge_logs.py worker-a.log worker-b.log -o merged.jsonl
python3 - <<'PYCODE'
import json
from pathlib import Path
rows = [json.loads(line) for line in Path("merged.jsonl").read_text(encoding="utf-8").splitlines()]
assert [r["message"] for r in rows] == [
    "alpha started", "beta started", "beta finished", "alpha finished"
]
assert rows[0]["time"] == rows[1]["time"] == "2026-10-28T00:00:00+00:00"
assert [r["line"] for r in rows] == [1, 1, 2, 2]
print("PASS: merged timeline and source line numbers")
PYCODE
The success report is {"records": 4, "output": "merged.jsonl"}, followed by PASS: merged timeline and source line numbers. Each JSONL row contains time, source, line, and message; JSON encoding handles quotes and backslashes in messages. Line endings become LF. An input’s last line can lack a newline, while every output record has one.
- Deliberately supply a backwards log:
cat > backwards.log <<'EOF'
2026-10-28T00:00:03Z later
2026-10-28T00:00:01Z earlier
EOF
python3 merge_logs.py worker-a.log backwards.log -o rejected.jsonl
printf 'exit=%s\n' "$?"
python3 -c 'from pathlib import Path; assert not Path("rejected.jsonl").exists()'
Expect backwards.log:2: timestamps go backwards, exit status 2, and no rejected.jsonl. Do not hide failures with || true. A script using set -e stops at this intentional failure, so run these demonstration commands interactively one at a time.
Success returns 0; input, output, and argument errors return 2. Process the artifact only after success:
python3 merge_logs.py worker-a.log worker-b.log -o next-run.jsonl && wc -l next-run.jsonl
5. Validation: boundaries and failure protection
Save the following as check_merge.py and run python3 check_merge.py beside merge_logs.py. It creates files only in an automatically cleaned subdirectory and checks ordering, offsets, ties, Unicode, CRLF, missing final newlines, empty input, invalid encoding, backwards timestamps, missing paths, and existing-output protection.
import json
from pathlib import Path
import subprocess
import sys
import tempfile

script = Path("merge_logs.py").resolve()
with tempfile.TemporaryDirectory(prefix="merge-check-", dir=".") as folder:
    root = Path(folder)
    a, b, output = [root / name for name in ("a log.txt", "b.log", "result.jsonl")]
    a.write_text("2026-10-28T08:00:00+08:00 alpha\n"
                 "2026-10-28T00:00:02Z 中文", encoding="utf-8")
    b.write_bytes(b"2026-10-28T00:00:00Z beta\r\n"
                  b"2026-10-28T00:00:01Z gamma\r\n")
    original = (a.read_bytes(), b.read_bytes())

    def run(inputs, destination):
        return subprocess.run([sys.executable, str(script), *map(str, inputs),
                               "-o", str(destination)], capture_output=True,
                              text=True, encoding="utf-8")

    result = run([a, b], output)
    assert result.returncode == 0 and json.loads(result.stdout)["records"] == 4
    rows = [json.loads(line) for line in output.read_text(encoding="utf-8").splitlines()]
    assert [r["message"] for r in rows] == ["alpha", "beta", "gamma", "中文"]
    assert [r["line"] for r in rows] == [1, 1, 2, 2]
    assert rows[0]["time"] == rows[1]["time"] == "2026-10-28T00:00:00+00:00"
    assert rows[0]["source"] == str(a) and rows[1]["source"] == str(b)
    saved = output.read_bytes()
    assert run([a, b], output).returncode == 2 and output.read_bytes() == saved
    assert run([a], a).returncode == 2
    assert (a.read_bytes(), b.read_bytes()) == original

    bad = root / "bad.log"
    failures = [
        b"2026-10-28T00:00:02Z later\n2026-10-28T00:00:01Z earlier\n",
        b"2026-10-28T00:00:00 no-offset\n",
        b"not-a-timestamp message\n", b"\n", b"2026-10-28T00:00:00Z\n",
        b"2026-10-28T00:00:00Z \xff\n",
    ]
    for index, payload in enumerate(failures):
        bad.write_bytes(payload)
        target = root / f"failed-{index}.jsonl"
        result = run([a, bad], target)
        assert result.returncode == 2 and not result.stdout and result.stderr
        assert not target.exists() and bad.read_bytes() == payload
    missing = run([root / "missing.log"], root / "missing.jsonl")
    assert missing.returncode == 2 and not (root / "missing.jsonl").exists()
    assert run([a, a], root / "duplicate.jsonl").returncode == 2
    assert run([a] * 65, root / "too-many.jsonl").returncode == 2
    empty = root / "empty.log"
    empty.write_bytes(b"")
    empty_output = root / "empty.jsonl"
    assert run([empty], empty_output).returncode == 0
    assert empty_output.read_bytes() == b""
print("PASS: ordering, offsets, ties, Unicode, line endings, failures, output protection")
Empty input here means an input file with no content: it produces empty JSONL and a report of zero records. Two equal-time messages remain separate records; the output count should equal the total valid input lines. You can also apply the line-by-line JSONL validator downstream.
6. Troubleshooting: act on the error
| Error | Action |
|---|---|
timestamps go backwards |
Inspect the reported path and line. Sort that file by actual instant first or fix its writer. Keep the check enabled. |
timestamp needs Z or a UTC offset |
Confirm the timezone at the source and add the correct offset; do not guess from the server setting. |
expected TIMESTAMP message |
Repair empty records and convert multiline stack traces to the agreed single-line format. |
File exists |
Choose a new output name. Preserve older reports that are still useful. |
| UTF-8 decoding failure | Identify the source encoding and convert explicitly; avoid dropping content with errors="ignore". |
Too many open files or insufficient disk space |
Reduce inputs per batch and check free space. For more than 64 files, merge batches first; convert the intermediate JSONL back to this tool’s input format before another merge stage. |
This is not tail -f: it does not wait for new records or correct server clock skew. If concurrent writers produce an unsorted file, prepare a sorted stable copy first. Uniform timestamp formatting alone does not establish ordering.
7. Summary
Normalize timestamps to UTC and verify each input’s ordering before merging records with heapq.merge. Preserve source locations and create new output after full validation to make troubleshooting easier. Check exit status and record counts before downstream automation reads the completed result.
- Author: yanzhi
- Original article: https://www.bobobk.com/en/python-merge-sorted-logs-heapq.html
- License: This work is licensed under CC BY-NC-ND 4.0. See the license for attribution, noncommercial use and no-derivatives terms.