用 Python 可靠下载文件:流式读取、大小上限与 SHA-256 校验
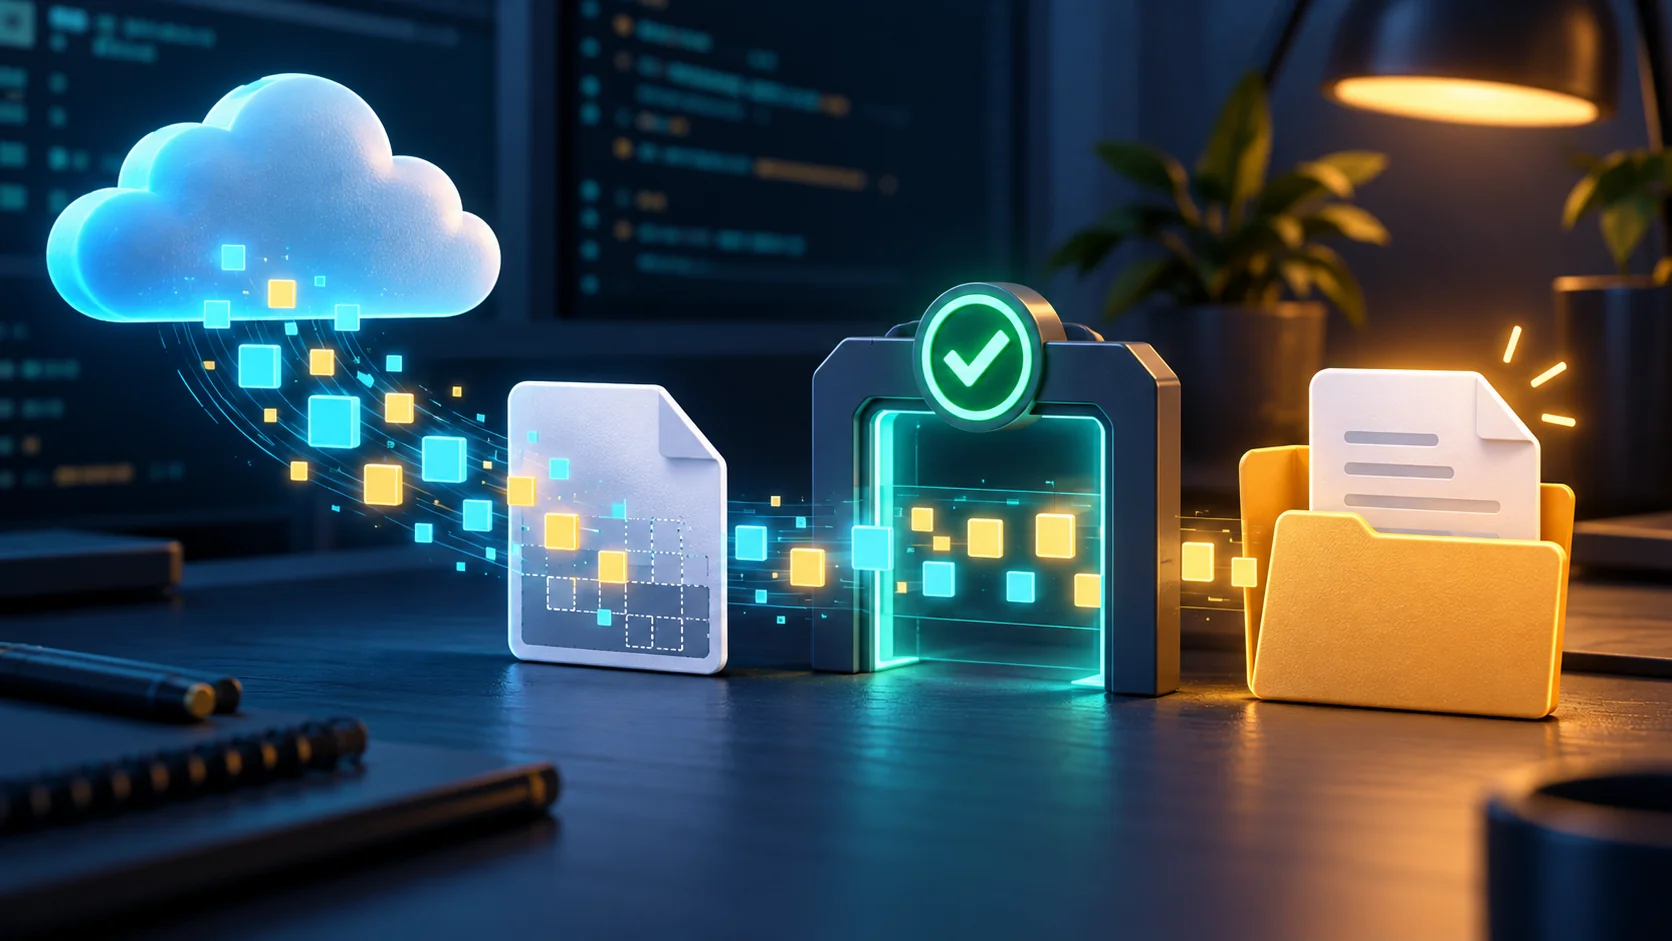
定时任务先打开 data.csv,再从网络往里写;下载中断后,原来的完整文件已经被截断,下游还可能把半个文件当成新结果。本文用 Python 标准库实现一个下载器:分块读取、限制大小、验证 SHA-256,全部通过后才替换目标文件。
示例面向初学者到中级读者,适合下载已知来源的数据导出和发布包。它只尝试一次,不续传、不自动重试;如果需要小型 JSON 接口的重试策略,可以先看 HTTP JSON 超时与有限重试。
1. 方法:先验证,再替换
下载顺序如下:
- 只接受 HTTP(S) URL 和 HTTP 200;重定向直接失败,便于明确实际来源。
- 在目标文件的同一目录创建随机
.part文件,每次最多读取 64 KiB。 - 同时统计字节数和 SHA-256;有
Content-Length时还要核对长度。 - 长度、大小上限和可信校验和都通过后,刷新、关闭临时文件,再替换目标。
- 可捕获的异常发生时清理临时文件,返回非零退出码。
Content-Length 可能缺失,长度也不能证明内容正确,因此始终执行字节上限和 SHA-256 检查。校验和需要从发布方的可信渠道获取;不要下载完后对同一份结果算一个 hash,再拿它证明自己正确。已有文件清单的用法见 SHA-256 数据清单检查。
2. 准备环境
需要 Python 3.10 或更新版本;下载示例脚本的命令还需要 curl。无第三方 Python 依赖,下面的代码和故障自检已在 Linux、Python 3.11.4 验证。使用一个新的练习目录:
python3 --version
mkdir stream-download-demo
cd stream-download-demo
curl -fS https://www.bobobk.com/downloads/stream-download/download_file.py -o download_file.py
curl -fS https://www.bobobk.com/downloads/stream-download/selftest.py -o selftest.py
python3 download_file.py --help
也可手动保存下一节完整代码为 download_file.py。selftest.py 是配套的完整本地测试,不会请求外部数据源。
目标的父目录必须已经存在。只在自己控制的可信目录里运行,并确保同一目标只有一个写入者。
3. 完整实现
"""Download one known HTTP(S) file and verify SHA-256 before replacing it."""
import argparse
import hashlib
from http.client import HTTPException
import json
import math
import os
from pathlib import Path
import re
import sys
import tempfile
from urllib.parse import urlsplit
from urllib.request import HTTPRedirectHandler, Request, build_opener


class NoRedirect(HTTPRedirectHandler):
    def redirect_request(self, req, fp, code, msg, headers, newurl):
        return None


def download(url, target, expected_sha256, max_bytes, timeout):
    parts = urlsplit(url)
    if parts.scheme not in {"http", "https"} or not parts.hostname:
        raise ValueError("URL must use http:// or https:// with a host")
    target = Path(target).absolute()
    temporary = None
    request = Request(url, headers={"Accept-Encoding": "identity"})
    try:
        with build_opener(NoRedirect()).open(request, timeout=timeout) as response:
            if response.status != 200:
                raise ValueError(f"expected HTTP 200, got {response.status}")
            if response.headers.get("Content-Encoding", "identity").lower() != "identity":
                raise ValueError("unexpected Content-Encoding")
            lengths = response.headers.get_all("Content-Length", [])
            if lengths and (len(lengths) != 1 or not re.fullmatch(r"[0-9]+", lengths[0])):
                raise ValueError("invalid Content-Length")
            declared = int(lengths[0]) if lengths else None
            if declared is not None and declared > max_bytes:
                raise ValueError("Content-Length exceeds --max-bytes")
            digest = hashlib.sha256()
            total = 0
            with tempfile.NamedTemporaryFile(
                dir=target.parent, prefix=f".{target.name}.",
                suffix=".part", delete=False,
            ) as output:
                temporary = Path(output.name)
                while True:
                    chunk = response.read(min(65536, max_bytes - total + 1))
                    if not chunk:
                        break
                    total += len(chunk)
                    if total > max_bytes:
                        raise ValueError("body exceeds --max-bytes")
                    output.write(chunk)
                    digest.update(chunk)
                if declared is not None and total != declared:
                    raise ValueError("Content-Length mismatch (truncated response)")
                actual = digest.hexdigest()
                if actual != expected_sha256:
                    raise ValueError("SHA-256 mismatch")
                output.flush()
                os.fsync(output.fileno())
        os.replace(temporary, target)
        temporary = None
        return {"file": str(target), "bytes": total, "sha256": actual}
    finally:
        if temporary is not None:
            temporary.unlink(missing_ok=True)


def main():
    parser = argparse.ArgumentParser(description=__doc__, allow_abbrev=False)
    parser.add_argument("url")
    parser.add_argument("output", type=Path)
    parser.add_argument("--sha256", required=True, help="trusted 64-digit SHA-256")
    parser.add_argument("--max-bytes", type=int, required=True)
    parser.add_argument("--timeout", type=float, default=10.0,
                        help="blocking socket operation timeout, seconds (default: 10)")
    args = parser.parse_args()
    if not re.fullmatch(r"[0-9a-fA-F]{64}", args.sha256):
        parser.error("--sha256 must have exactly 64 hexadecimal digits")
    if args.max_bytes < 1:
        parser.error("--max-bytes must be positive")
    if not math.isfinite(args.timeout) or args.timeout <= 0:
        parser.error("--timeout must be finite and positive")
    try:
        result = download(args.url, args.output, args.sha256.lower(),
                          args.max_bytes, args.timeout)
    except (OSError, ValueError, HTTPException) as exc:
        print(f"ERROR: {exc}", file=sys.stderr)
        return 1
    print(json.dumps(result, ensure_ascii=False))
    return 0


if __name__ == "__main__":
    raise SystemExit(main())
NamedTemporaryFile 创建临时文件,指定 dir=target.parent 可把它放在目标旁边。os.replace() 在同一文件系统成功替换时具有原子性;本例的保存思路也可用于 JSON 原子写入。
hashlib.update() 可逐块更新摘要,无需把整个文件装入内存。--max-bytes 限制写入的响应体字节数;在边界处最多额外读一个字节来判断是否超限。脚本请求原始编码,若服务端仍返回非 identity 的 Content-Encoding 就拒绝,避免把传输编码后的字节与另一种表示的 hash 混用。
urlopen 的超时说明适用于这里 opener 使用的底层阻塞网络操作。--timeout 3 不是整个下载必须在三秒内结束:持续有数据的慢速传输仍可运行更久,DNS 解析也不一定受这个参数约束。脚本沿用系统代理和默认 HTTPS 证书验证;它只用于你认可的 URL,不接受不可信用户提交的地址。
4. 本地执行与验证
- 在练习目录的终端 A 创建一个测试源文件并启动本地服务:
mkdir source
printf 'id,value\n1,42\n' > source/data.csv
python3 -m http.server 8765 --bind 127.0.0.1 --directory source
保持终端 A 运行。服务只监听本机;若 8765 已占用,给服务器和下面的 URL 同时换一个端口。结束练习时在终端 A 按 Ctrl+C。
- 在终端 B 进入同一个
stream-download-demo目录,再运行:
export no_proxy=127.0.0.1,localhost
export NO_PROXY=127.0.0.1,localhost
download_sha=$(python3 -c 'import hashlib; from pathlib import Path; print(hashlib.sha256(Path("source/data.csv").read_bytes()).hexdigest())')
python3 download_file.py http://127.0.0.1:8765/data.csv result.csv \
  --sha256 "$download_sha" --max-bytes 1048576 --timeout 3
python3 - <<'PY_CHECK'
from pathlib import Path
assert Path("result.csv").read_bytes() == b"id,value\n1,42\n"
assert not list(Path(".").glob(".result.csv.*.part"))
print("PASS: exact contents; no partial file")
PY_CHECK
这里的 hash 来自你刚创建的源文件,用于演示可信预期值;实际下载应使用发布方给出的校验和。两条代理环境变量只影响当前终端和子进程,使本机测试不经过代理。
成功时先输出一行 JSON,包含目标绝对路径、bytes: 14 和 sha256,然后打印 PASS: exact contents; no partial file。再次运行会用验证后的内容替换 result.csv。
| 退出码 | 含义 |
|---|---|
| 0 | 下载与校验完成,目标已替换;stdout 为一行 JSON。 |
| 1 | 网络、响应、校验或文件系统操作失败;错误写 stderr,无成功 JSON。 |
| 2 | 参数无效,例如错误的 hash、非正数上限或无限超时。 |
5. 故障自检:确认旧文件没有被破坏
在终端 B 执行配套测试;它会自行启动随机端口的本地 HTTP 服务,用临时目录测试,结束后自动关闭服务并删除测试文件:
python3 selftest.py
预期输出:
PASS: 2 successes, 8 failures preserve old output; no partial files
PASS: failed first download leaves no output; 3 invalid arguments rejected
测试覆盖有无 Content-Length 的成功下载,以及 hash 不匹配、截断、声明大小超限、实际大小超限、404、302、意外编码和超时。每次失败都检查退出码、stderr、旧文件内容和 .part 清理;另检查首次下载失败不会创建正式目标,错误参数返回 2。
测试用可控响应复现故障,无需断开真实网络。它不会修改第 4 节的 result.csv。
6. 接入自动化与排错
在终端 B 沿用第 4 节的变量和本地服务,用 && 让后续步骤只在下载成功后执行:
python3 download_file.py http://127.0.0.1:8765/data.csv result.csv \
  --sha256 "$download_sha" --max-bytes 1048576 --timeout 3 \
  && python3 -c 'from pathlib import Path; print(Path("result.csv").read_text())'
生产任务应把 URL、目标路径、可信 hash 和上限设为自己的实际值,并由既有任务入口调用。hash 不匹配时即使旧文件仍在,也必须停止本轮后续操作,不能因为“文件存在”就继续。
| 现象 | 具体处理 |
|---|---|
SHA-256 mismatch |
确认发布版本与可信 hash 对应;保留旧文件,核对来源后再下载。不要自动采用本次失败文件的摘要。 |
truncated response |
重新获取完整响应,检查代理或源服务的中断记录。 |
Content-Length exceeds / body exceeds |
检查是否拿到了错误资源;确认预期大小后再调整上限。 |
| HTTP 301/302 | 核实发布方公布的最终地址,显式使用该地址;脚本不会跟随跳转。 |
timed out |
检查网络和源服务,再按实际情况调整单次操作超时。 |
Permission denied / 目录不存在 |
检查目标父目录与运行账号;先在明确可写的练习目录复现。 |
unexpected Content-Encoding |
使用提供原始文件字节的下载入口,并确认 hash 对应相同表示。 |
临时文件在 Linux 通常只有所有者可读写,替换后不会继承旧文件的权限;需要其他进程读取时,在可信流程里显式设置合适权限。原子替换只保证读者看到完整的旧文件或新文件,不保证业务数据正确、并发写入有序或断电后的目录持久性。finally 也不能在 SIGKILL、进程崩溃或断电后运行,可能遗留随机 .part;先确认没有活动下载,再检查和清理对应文件。
7. 小结
把正式文件的替换放到下载和校验之后,可以避免网络故障破坏上一次完整结果。分块读取控制内存,字节上限控制写入量,可信 SHA-256 用于核对内容。先运行本地故障自检,再把成功退出码作为后续自动化的前提。
- 原文作者:春江暮客
- 原文链接:https://www.bobobk.com/python-stream-download-sha256.html
- 版权声明:本作品采用 知识共享署名-非商业性使用-禁止演绎 4.0 国际许可协议 进行许可,非商业转载请注明出处(作者,原文链接),商业转载请联系作者获得授权。